
As voice AI moves from assistants toward agents that can execute tasks, reducing the silence between a user’s words and an AI response is becoming a broader systems challenge.
Voice AI is entering a different phase. The industry has made substantial progress in recognizing speech, interpreting natural language and generating increasingly realistic voices. Yet real-world voice interaction remains constrained by a problem that is less visible in model benchmarks: how long a user has to wait before the system responds.
A 2025 measurement study of six human-to-generative-AI calling applications from Google, Meta, Microsoft and OpenAI found that conversational latency could reach several seconds, considerably longer than the sub-second delays typical of human-to-human voice communication. The researchers identified latency optimization, network infrastructure and resilience under load as important challenges for voice applications.
That gap matters because voice is less forgiving than text. A delayed answer on a screen can feel like processing time. A long silence on a call can feel like the system has stopped listening.
For early-stage voice AI builders, that changes the engineering problem. Harshil Mistry, founder of Velox AI, sees the shift from the perspective of building a real-time voice platform.
“The biggest surprise isn’t that the models got smarter, it’s that the latency floor dropped so aggressively. Just recently, chaining speech-to-text, LLM, and text-to-speech meant accepting a 1-second delay. Today, sub-300ms end-to-end latency is the baseline for a natural conversation. This shift directly shaped Velox AI. We couldn’t just build a wrapper; we had to engineer a real-time orchestrator using WebSockets and token streaming to eliminate network hops. It forced us to treat milliseconds as our most critical resource.”
While conversing with KoreaTechToday, Mistry’s observation reflects the experience of one early-stage founder, rather than an established industry benchmark. Independent measurements suggest that actual caller-facing latency can still be considerably higher.
Voice Latency Is an End-to-End Problem
Part of the difficulty is that voice latency is not determined by a single model.
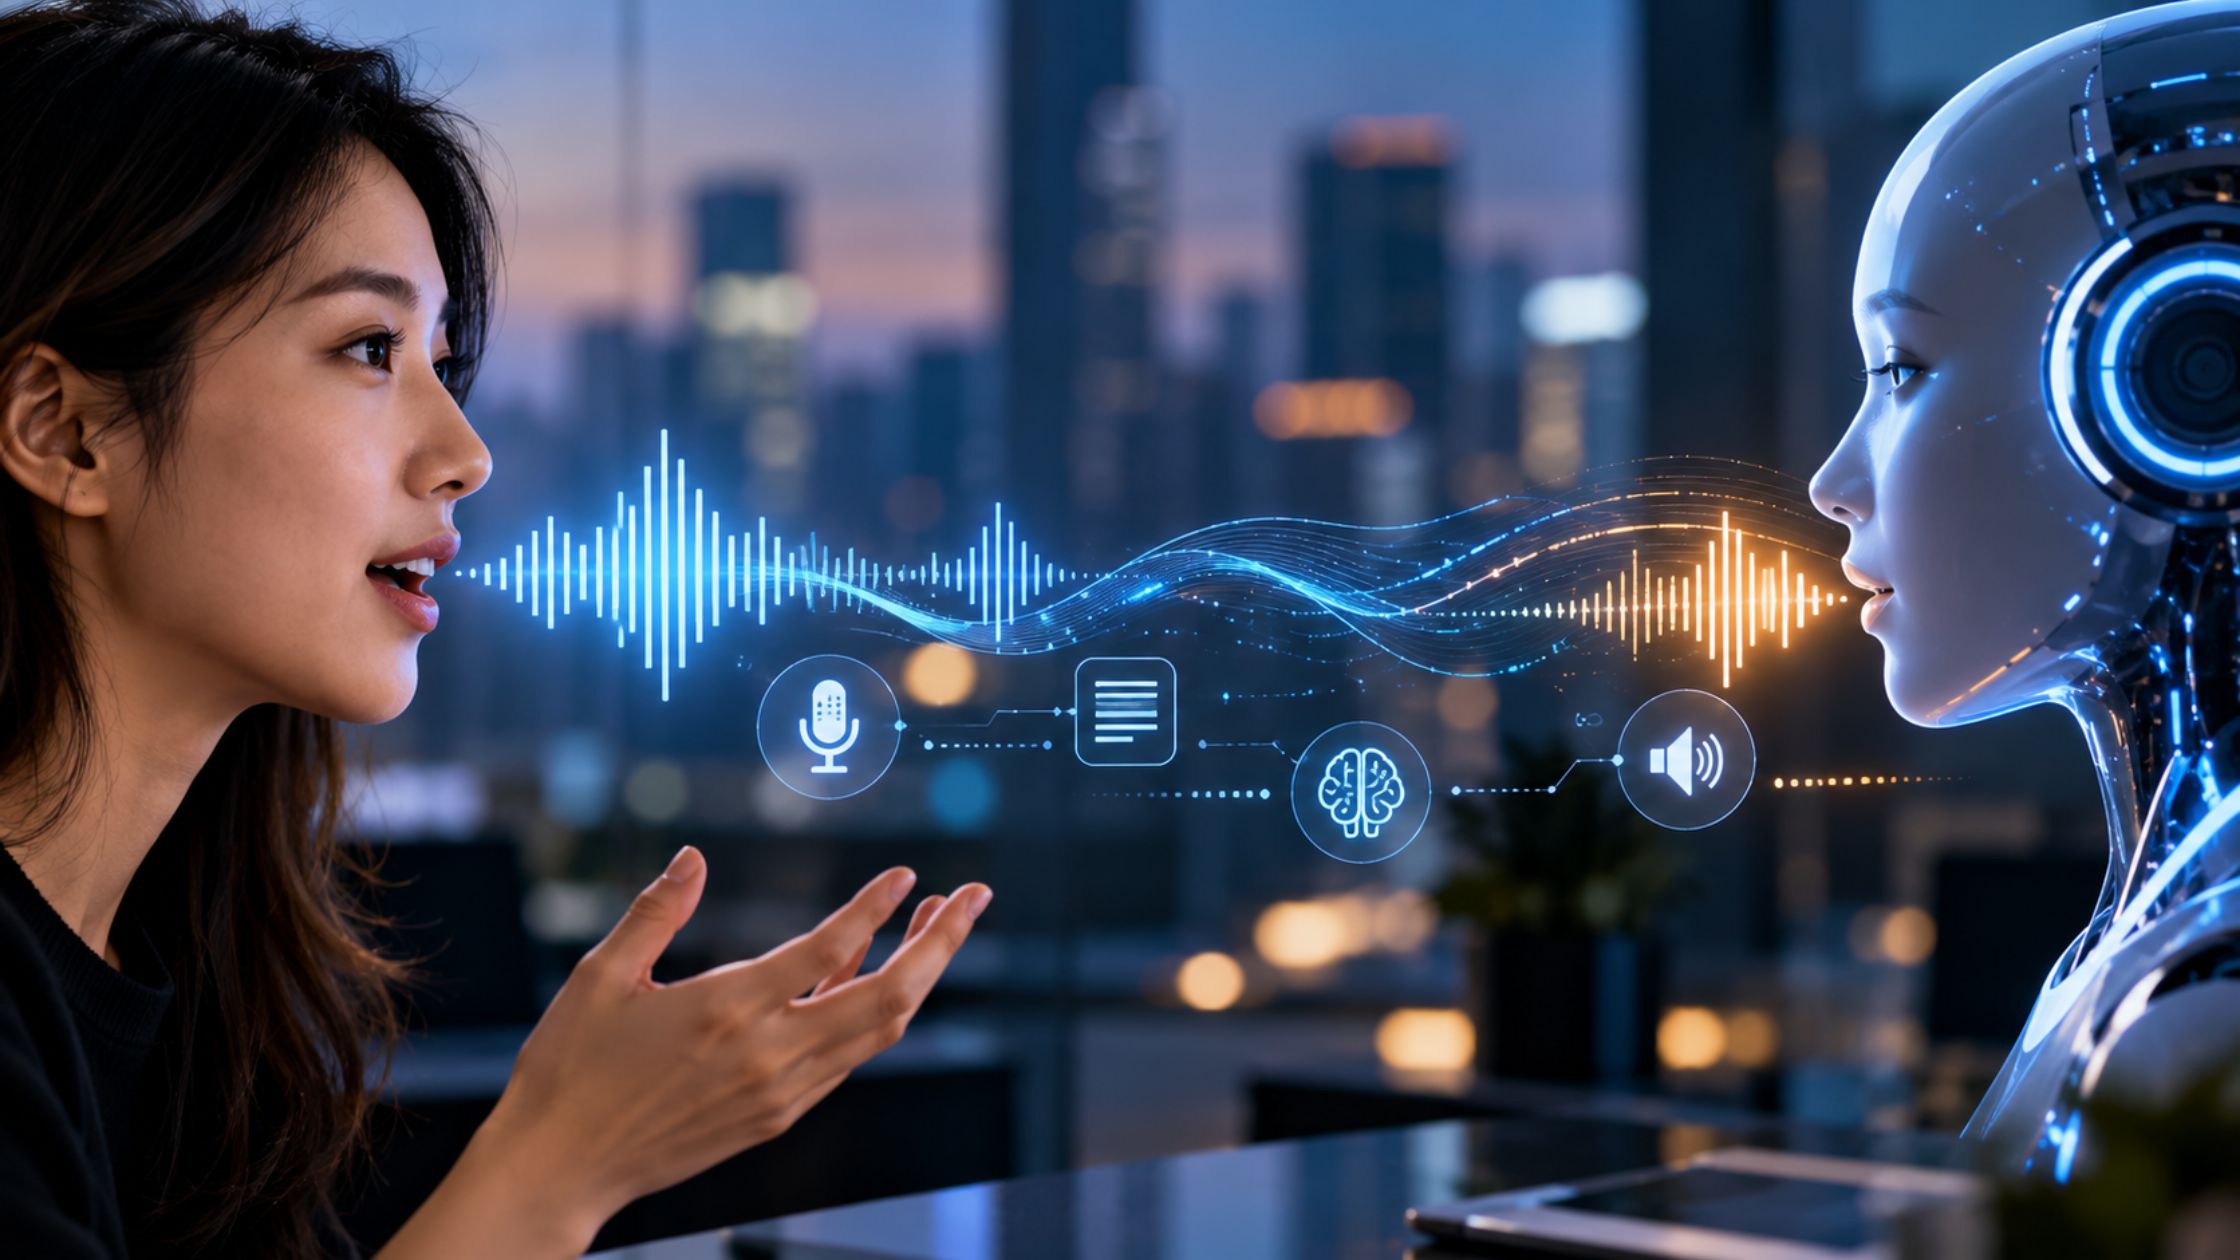
In a conventional architecture, a spoken request can move through several stages: speech recognition, language-model processing and speech synthesis. Each stage introduces processing time, while network transmission, audio buffering and the system’s decision about when the user has finished speaking add further delays.
Newer systems are therefore experimenting with more tightly integrated and streaming architectures. Research presented at the 2026 International Conference on Machine Learning found that streaming tool use in speech-to-speech systems could reduce latency by up to 57% while also improving question-answering accuracy. The research illustrates a broader trend: reducing conversational delay increasingly requires work across the entire pipeline, rather than simply choosing a faster language model.
Even the way latency is measured matters. An open benchmark based on actual phone calls currently reports median time-to-first-audio of roughly 1.3 to 1.7 seconds across several commercial voice-agent platforms, with some platforms exceeding two seconds at the 95th percentile. These measurements capture the silence experienced by a caller rather than relying solely on platform-reported timestamps.
The difference is significant. An AI system can have extremely fast model inference and still feel slow if endpoint detection, networking or speech generation introduces additional waiting time.
The Korean Market Is Moving Voice Toward Action
This issue is becoming particularly relevant as Korean technology companies move voice AI beyond simple commands and toward agentic interactions.
Samsung has evolved Bixby into a conversational device agent that can understand natural-language requests and execute actions across Galaxy devices. Samsung describes the system as part of a broader shift from conventional voice assistance toward agents that understand context and perform tasks for users.
Hyundai Motor Group is taking a similar approach inside vehicles. Its Pleos Connect system incorporates Gleo AI, an LLM-based voice assistant that can understand conversational and driving context, process multiple commands, search the web and control vehicle functions. Hyundai plans to expand Pleos Connect across next-generation vehicles, with a target of approximately 20 million equipped vehicles by 2030.
Kakao is also working on the speech-generation layer. Its Kanana-o model has been upgraded to provide finer control over speaking style, speed, emotion and intonation, while a proprietary speech tokenizer is intended to improve generation speed and efficiency.
Meanwhile, South Korea’s government-backed AI for All initiative is pushing SK Telecom, Kakao and KT toward AI services that can move beyond answering questions to handling tasks such as information searches, applications, reservations and payments through familiar channels including phone and messaging.
As AI begins to do things through voice, delays become more consequential. The interaction is no longer simply about producing an answer. It becomes part of a workflow.
Speed Alone Will Not Make Voice AI Natural
Lower latency is necessary, but it does not solve the entire voice-AI problem. A 2026 benchmark of full-duplex voice agents evaluated 278 real-world tasks and found that voice agents achieved substantially lower task-completion rates than the underlying text model, particularly under realistic conditions involving noise and diverse accents. The research suggests that agent behavior, not just speech quality, remains a major source of failure.
That points toward a broader definition of voice-AI performance. Developers increasingly need to consider not just how quickly an agent responds, but whether it understands when someone has finished speaking, handles interruptions, maintains context, executes the requested task and recovers when something goes wrong. For Korean technology companies building AI into phones, vehicles, services and enterprise workflows, these factors could become as important as the underlying model.
The Next Voice-AI Benchmark Is the Conversation
The industry’s progress in speech recognition and generative models has changed what users expect from voice interfaces. The technical challenge is now increasingly about coordinating all the components quickly enough to sustain a natural exchange. That does not mean every voice system needs to reach one universal latency number. It means developers have to optimize for the experience the user actually perceives.
The next generation of voice AI will therefore be judged less by whether a machine can hear, understand and speak in isolation, and more by whether the entire conversation works. For an early-stage builder like Mistry, that realization is already influencing how a voice platform is being engineered. For the wider industry, it points to a more difficult transition: making AI conversational is no longer only a model problem. It is a real-time systems problem involving models, networks, audio, orchestration and, ultimately, the user’s patience.