
As Korean companies move AI agents from demonstrations toward real-world tasks, interruptions, ambiguity and unexpected user behavior are exposing a harder challenge than simply making machines sound natural.
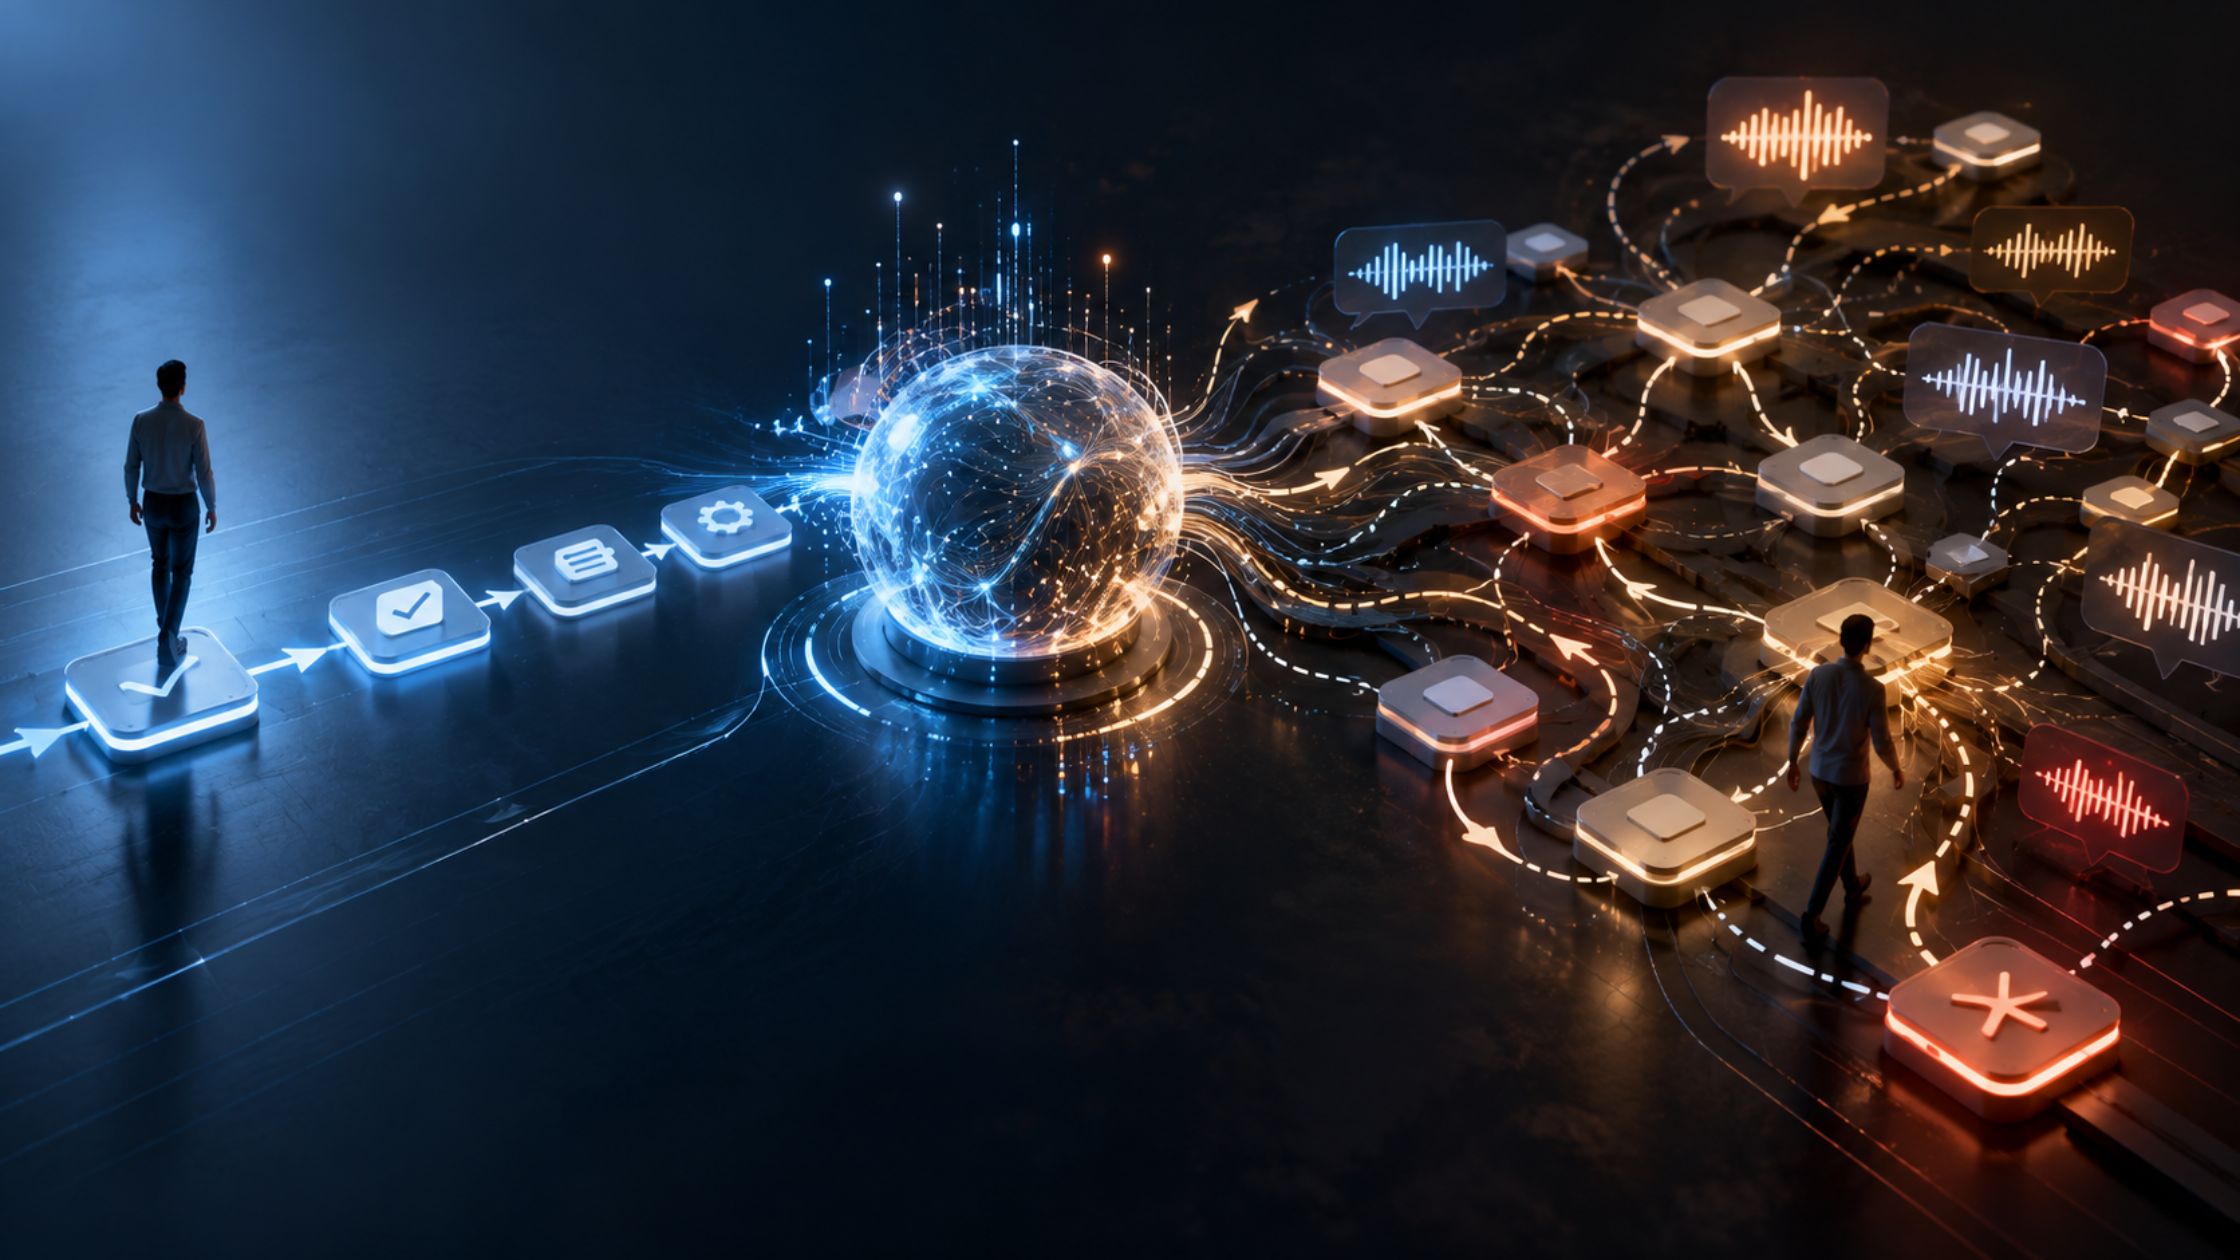
The most revealing test for an AI agent may not be whether it can hold a convincing five-minute conversation. It may be what happens when the person on the other end suddenly changes the conversation. That distinction is becoming increasingly important as AI agents move from answering questions to taking actions. A 2026 ICML benchmark, τ-Voice, evaluated full-duplex voice agents on 278 grounded tasks involving multi-turn conversations, domain policies, environmental interaction, realistic audio, accents and complex turn-taking. Under clean conditions, voice agents achieved 31% to 51% performance in the benchmark’s evaluated settings. Under more realistic conditions, performance fell to 26% to 38%.
The results point to a broader problem. AI agents may perform convincingly when interactions follow an expected pattern, but real customers rarely do.
The Shift From Conversation to Execution
This matters because the role of AI agents is changing. A conventional chatbot primarily needs to produce an appropriate response. An agent increasingly needs to understand intent, maintain context, select tools, execute actions and determine whether the requested outcome has actually been achieved. Samsung’s evolution of Bixby illustrates this transition. The company describes the new Bixby as a device agent capable of understanding device context, connecting functions and executing complex tasks through natural-language interaction. Samsung has also expanded Bixby’s ability to search the web within a conversational flow.
South Korea’s broader AI strategy is moving in the same direction. The Ministry of Science and ICT selected consortiums led by SK Telecom, Kakao and KT for its AI for All project, with nationwide services planned following agreements and beta services. The initiative is intended to make AI services accessible more broadly rather than limiting them to experimental use cases.
As these systems become capable of taking actions, however, a misunderstanding has different consequences. A wrong answer can be corrected in the next message. A wrong action may create a booking, change a setting, initiate a transaction or otherwise affect a user’s real-world activity.
The Hard Part Is What Happens After an Interruption
Human conversation is full of interruptions that are meaningful rather than accidental. A customer may say, “Book it for Tuesday,” then immediately add, “Actually, Wednesday works better.” Someone may interrupt an explanation to ask a question, correct a detail or introduce information that changes the original request.
The agent therefore has to do more than stop speaking. It needs to understand what changed. That distinction is now appearing in AI-agent evaluation itself. IHBench, introduced in 2026, specifically measures post-interruption recovery rather than simply whether an agent can detect an interruption and stop talking. Its evaluation covers 428 interruption samples, six interruption types and 10 enterprise domains, treating recovery quality and task fulfillment as separate dimensions.
While conversing with KoreaTechToday, Harshil Mistry, founder of Velox AI, identified this as one of the biggest uncertainties facing voice agents:
“I am most focused on how agents handle the messy, unpredictable nature of human interruptions. In a demo, an AI speaks perfectly and the human waits their turn. On a real customer call, people talk over each other, change their minds mid-sentence, and call from noisy environments. Even with optimal sub-500ms response times, maintaining conversational context and executing a tool call without hallucinating is incredibly difficult. Bridging that gap between a clean sandbox and a chaotic live call is where the real friction lies.”
Mistry’s observation comes from an early-stage builder working on voice-agent infrastructure, rather than from a large-scale production benchmark. But it points directly toward an increasingly important distinction in how these systems should be evaluated.
Voice Quality Is Not the Same as Task Reliability
The industry has spent considerable effort reducing latency and improving the naturalness of synthetic speech. Those remain important because long pauses and awkward turn-taking can make voice interactions frustrating.
But an agent can sound natural and still fail at the actual task. There are at least three separate layers of performance:
- Voice quality: Does the system sound natural and respond appropriately?
- Conversational reliability: Can it preserve context, interpret interruptions and recover when the conversation changes?
- Task reliability: Can it execute the requested action correctly and verify the outcome?
The τ-Voice benchmark is significant because it evaluates grounded task completion alongside conversational dynamics, rather than treating a convincing dialogue as sufficient evidence of success. Its results suggest that realistic audio and turn-taking introduce challenges that are not captured by simpler evaluations.
For Korean enterprises deploying agents, the distinction becomes particularly relevant as systems move closer to everyday services and device control.
Korea’s Agentic AI Push Raises the Stakes
Korea’s AI ecosystem is moving rapidly toward this more autonomous model. Samsung is extending Bixby across its device ecosystem, positioning it as an interface through which users can describe what they want rather than navigate individual settings manually.
Meanwhile, SK Telecom, KT and Kakao are developing services under the government’s AI for All initiative. Their involvement indicates that agentic AI is being considered not only as a productivity tool but as an interface for broader consumer and public-facing services. That makes reliability under unpredictable interaction more than a voice-interface problem. It becomes an infrastructure and product-design problem.
Enterprises will increasingly need to ask whether an agent can recover after an interruption, preserve the latest instruction, execute the correct tool call, recognize uncertainty and hand a conversation to a human when necessary. Average performance will not tell the whole story either. A system that handles most routine conversations successfully can still create serious operational problems if a small number of edge cases result in incorrect actions.
The Next Benchmark Is the Messy Conversation
AI agents are entering a phase where sounding human is no longer the only measure of progress. The more consequential question is whether they can remain reliable when humans behave like humans. That means changing their minds, speaking over the system, correcting themselves, introducing unexpected information or communicating in environments that are far removed from a controlled demonstration.
For Korea, where companies and policymakers are actively pushing AI agents toward devices, services and everyday execution, this distinction will become increasingly important. The next generation of agents will not be judged only by how naturally they speak or how quickly they respond. They will be judged by what happens when the conversation stops going according to plan. The real test may begin precisely when the script ends.